
ARC-AGI-3 Scores Highlight AI Agents’ Reasoning Limits as Claude Dispatch Expands Prompt-Injection Risk
Summary
The article reports frontier models scoring below 1% on ARC-AGI-3 and argues that Claude Dispatch’s claimed full filesystem access outside Cowork’s sandbox increases prompt-injection risk. It recommends least privilege, network segregation and assuming breach.
Key points
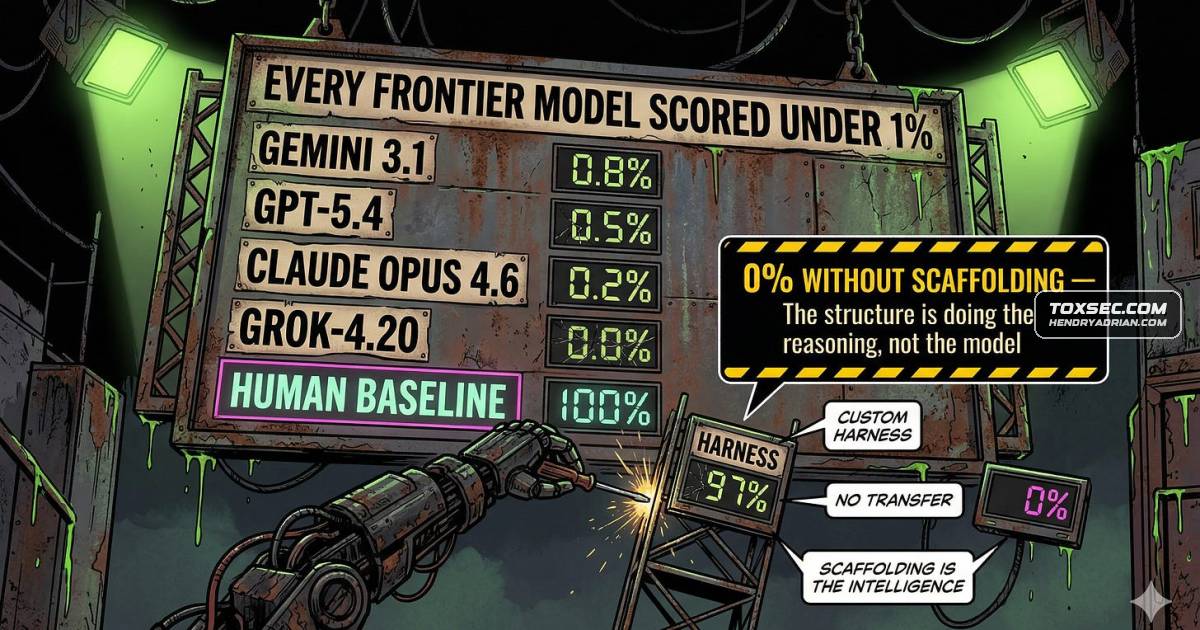
- The article reports that humans solved all 135 ARC-AGI-3 environments, while tested frontier models scored below 1%.
- It describes RHAE as penalizing inefficient action sequences and says models often brute-force exploration rather than form coherent strategies.
- The article says Claude Dispatch operates outside Cowork’s folder-scoped sandbox and has full filesystem reach.
- It warns that emails, documents and web content read by the agent could carry prompt-injection payloads with access to the machine.
- Recommended precautions include least-privilege access, dedicated network-segregated hardware and assuming breach.
Article Details
- Topic
- ARC-AGI-3 benchmark results and prompt-injection risks from Claude Dispatch’s full filesystem access
Vendors
Products
Claude DispatchAnthropic’s Claude Dispatch ships the ability for a phone to control a live desktop Claude session with full filesystem reach, amplifying prompt-injection risk and highlighting that these models lack the abstractClaude Opus 4.6Frontier models scored under 1% (Gemini 3.1 Pro 0.37%, GPT-5.4 0.26%, Claude Opus 4.6 0.25%, Grok-4.20 0%), while humans achieved 100%.CoworkClaude Dispatch operates outside Cowork’s sandbox with default full filesystem access, increasing the blast radius for prompt-injection and MCP-style poisoning attacks.Gemini 3.1 ProFrontier models scored under 1% (Gemini 3.1 Pro 0.37%, GPT-5.4 0.26%, Claude Opus 4.6 0.25%, Grok-4.20 0%), while humans achieved 100%.GPT-5.4-CyberFrontier models scored under 1% (Gemini 3.1 Pro 0.37%, GPT-5.4 0.26%, Claude Opus 4.6 0.25%, Grok-4.20 0%), while humans achieved 100%.Grok-4.20Frontier models scored under 1% (Gemini 3.1 Pro 0.37%, GPT-5.4 0.26%, Claude Opus 4.6 0.25%, Grok-4.20 0%), while humans achieved 100%.