
Multimodal Prompt Injections Hide Instructions in Images and Audio
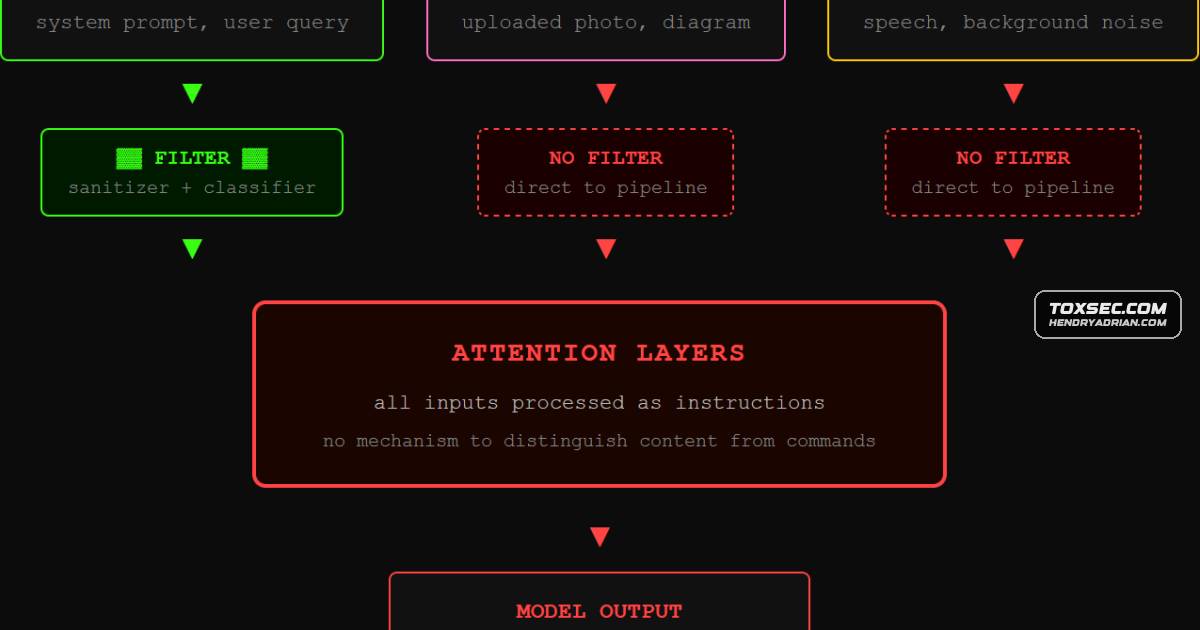
Summary
The article explains how image and audio prompt-injection techniques can bypass text-focused safeguards, citing research on cross-model transfer and high success rates in tests, including over-the-air audio attacks.
Key points
- Image-based techniques include typographic attacks such as FigStep, steganographic pixel changes, and instructions embedded in diagrams.
- The article says FigStep-Pro splits instructions across image tiles to evade OCR-based filters.
- It cites a study in which a steganographic technique achieved 31.8% success across tests while images remained visually unchanged.
- The article describes audio attacks that suppress transcription or inject hidden instructions, including the mute attack and WhisperInject.
- It reports WhisperInject success rates above 86% on Phi-4-Multimodal and Qwen2.5-Omni, with noise below the human hearing threshold.
- It says research tested adversarial audio over the air and reported 87–88% success under physical conditions.
Article Details
- Topic
- Image- and audio-based multimodal prompt injection against vision-language and audio-capable models
Products
ClaudeA 2025 study tested this against eight models including GPT-4V and Claude.GPT-4VA 2025 study tested this against eight models including GPT-4V and Claude.Phi-4-MultimodalThe WhisperInject framework achieves 86%+ success on Phi-4-Multimodal and Qwen2.5-Omni while keeping the noise below the human hearing threshold.Qwen2-AudioEvery model that processes speech input, Whisper-based pipelines, Qwen2-Audio, end-to-end voice agents, carries the same flaw as vision models: the audio gets converted into numbers the language model trusts asQwen2.5-OmniThe WhisperInject framework achieves 86%+ success on Phi-4-Multimodal and Qwen2.5-Omni while keeping the noise below the human hearing threshold.WhisperEvery model that processes speech input, Whisper-based pipelines, Qwen2-Audio, end-to-end voice agents, carries the same flaw as vision models: the audio gets converted into numbers the language model trusts as
Tools
CrossInjectThe CrossInject framework combined visual and text-based manipulation at ACM MM 2025, hitting a +30% improvement in attack success over prior methods.WhisperInjectThese techniques—typographic (FigStep), steganographic, semantic, and audio methods like WhisperInject—transfer across models, achieve high success rates in tests, and can be executed in the physical world.